Rent Turkey's most powerful cloud GPU infrastructure for your AI projects
Hourly and monthly dedicated GPU servers in our Istanbul Tier-IV datacenter for model training, fine-tuning, and large-scale inference.
Hourly and monthly dedicated GPU servers in our Istanbul Tier-IV datacenter for model training, fine-tuning, and large-scale inference.
Zero idle costs when there is no traffic, sub-second cold starts on the first request, and maximum token throughput powered by vLLM.
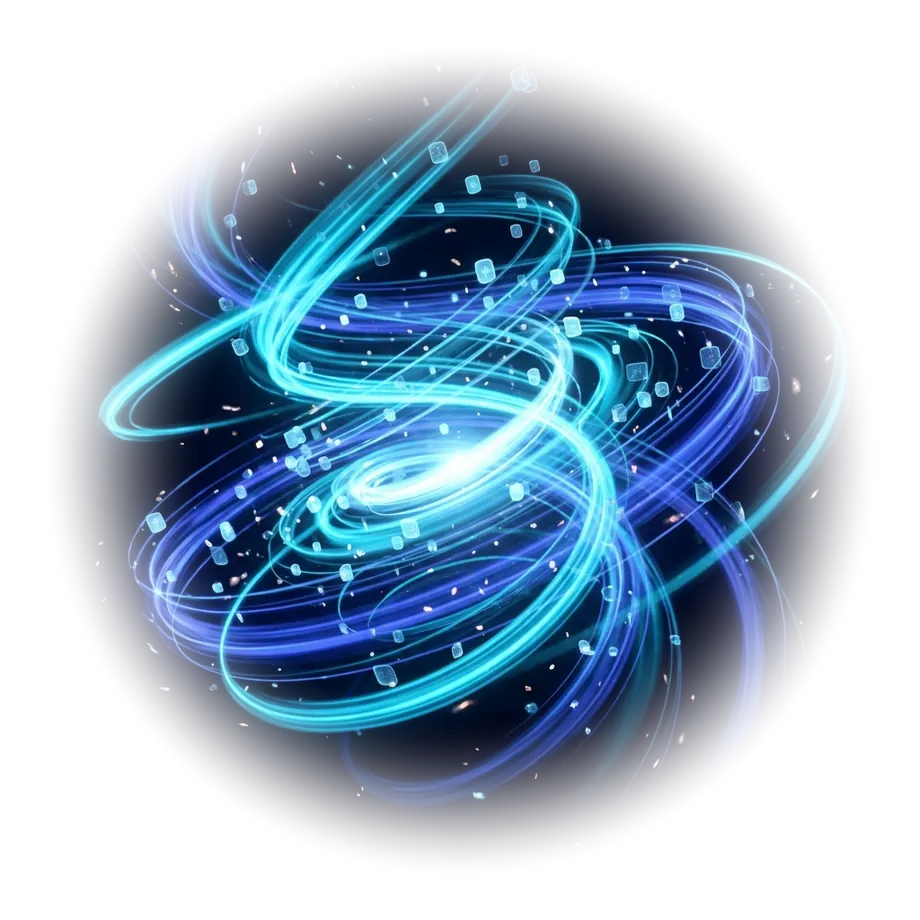
Cover your AI development, machine learning and high-performance computing needs without investing in hardware: NVIDIA GH200 Grace Hopper and RTX PRO 6000 Blackwell GPUs on HPE servers
Reach the newest accelerator technology with the NVIDIA GH200 Grace Hopper Superchip and RTX PRO 6000 Blackwell, and scale your AI application as far as you need.
Pick your GPU resource in the console.fixcloud.ai web interface and start working within minutes over secure access.
No upfront investment and no commitment: with hourly use you pay only for what you use, and a monthly commitment brings much lower prices.
Your data stays within Turkey, on 100% KVKK-compliant FixCloud infrastructure in the Equinix IL4 data center in Istanbul; you reach your GPU resources through a layered security architecture.
List, on-demand and committed prices for dedicated server, VM / container and serverless options
| GPU Model | Cards | VRAM | Service Model | List (Hourly) | On-Demand (Hourly) | Committed (Monthly) | Action |
|---|---|---|---|---|---|---|---|
|
NVIDIA GH200 Grace Hopper NVL2
2 × Superchip
|
2x GPU | 288 GB | Dedicated HPE DL 384 G12 | $19.99 | $9.99 | $6,999 | Rent → |
|
NVIDIA GH200 Grace Hopper
1 × Superchip
|
1x GPU | 144 GB | Dedicated VM / Container | $9.99 | $5.99 | $3,999 | Rent → |
|
NVIDIA GH200 Grace Hopper
4 Core · 72 GB MIG
|
MIG | 72 GB | Container / Serverless | $6.99 | $3.99 | $2,199 | Rent → |
|
NVIDIA GH200 Grace Hopper
2 Core · 36 GB MIG
|
MIG | 36 GB | Container / Serverless | $2.49 | $1.99 | $1,499 | Rent → |
|
NVIDIA GH200 Grace Hopper
1 Core · 18 GB MIG
|
MIG | 18 GB | Container / Serverless | $1.99 | $1.49 | $999 | Rent → |
|
NVIDIA RTX PRO 6000 Blackwell
1 card
|
1x GPU | 96 GB | Dedicated HPE DL 380a | $3.49 | $2.99 | $1,999 | Rent → |
|
NVIDIA RTX PRO 6000 Blackwell
2 cards
|
2x GPU | 192 GB | Dedicated HPE DL 380a | $9.49 | $5.99 | $4,999 | Rent → |
|
NVIDIA RTX PRO 6000 Blackwell
4 cards
|
4x GPU | 384 GB | Dedicated HPE DL 380a | $21.49 | $12.99 | $7,999 | Rent → |
Integrate large language models (LLMs) into your applications in minutes through a single API.
 OpenAI
 Qwen
 deepseek
 Mistral AI
 Meta
 Gemma 4
FixCloud LLMaaS delivers 10+ ready foundation models—including GPT-OSS, DeepSeek, Qwen, Llama, and Mistral—as a managed turnkey service on sovereign NVIDIA GPU infrastructure in Turkey. Generate your API key and deploy in minutes. Choose the monthly tier matching your workload and benefit from transparent pay-as-you-go metering for overage.
We deploy and host your fine-tuned model on dedicated GPUs with custom support and private endpoints.
| Model | Provider | Type | Context | Girdi $/1M | Output $/1M | Action |
|---|---|---|---|---|---|---|
|
OpenAI
|
chat | 128K | 0,99 | 2,99 | API kullan → | |
|
Alibaba
|
chat | 128K | 0,49 | 1,99 | API kullan → | |
|
Google
|
chat | 64K | 0,39 | 1,49 | API kullan → | |
|
DeepSeek
|
agent, coding | 256K | 1,49 | 3,49 | API kullan → | |
 Z.ai |
chat | 64K | 0,99 | 3,49 | API kullan → | |
|
Mistral AI
|
chat + vision | 64K | 1,49 | 3,99 | API kullan → | |
|
Meta
|
chat | 32K | 0,99 | 1,99 | API kullan → | |
|
OpenAI
|
speech to text | — | 1,49 | 2,49 | API kullan → | |
|
Alibaba
|
embedding | 32K | 0,39 | 0,99 | API kullan → | |
 BAAI |
reranking | 8K | 0,19 | 0,49 | API kullan → |
Generate your API key and launch in minutes. Transparent pay-as-you-go rates for usage beyond included quota.
For independent developers and starting projects.
For growing teams and enterprise applications.
For high-volume enterprise production inference.
Zero idle costs when traffic drops (scale-to-zero), sub-second cold starts on first request, and high token throughput powered by vLLM.
Intelligent KV-cache management that eliminates memory fragmentation, delivering 2 to 4x higher throughput and lower latency.
GPU resources automatically spin down to zero when idle. Pay strictly for the active seconds your models serve inference.
Dynamically groups incoming requests on the fly to minimize wait times and hardware cost per request.
Popular weights like Llama 3.3, Mistral, Qwen, and DeepSeek are pre-cached locally in our Istanbul datacenter for instant spin-up.
Process and store sensitive data locally with 100% KVKK and GDPR compliance without leaving national borders
No enterprise data ever leaves national borders. All model training, inference, and storage are hosted strictly in our Istanbul datacenters.
Real-time streaming via Syslog (UDP/TCP) and CEF directly to your internal enterprise SOC / SIEM systems.
AES-256 at rest and TLS 1.3 in transit end-to-end encryption standards ensuring maximum enterprise cybersecurity.
How do companies run their AI workloads on FixCloud without their data leaving Turkey? In our customers' own words.
HangiKredi, which compares financial products for millions of users, runs its agentic AI infrastructure and its Financial Assistant product on FixCloud LLMaaS and GPUaaS. Under KVKK and the Banking Law the data had to stay in the country; the team chose FixCloud on the performance results of tests and POCs it ran with many providers.
Read the full story →“It gave us the comfort of on-prem without having to bear the DevOps cost.”
All the answers to your questions about the FixCloud.AI sovereign cloud platform
base_url in your existing Python, Node.js, or cURL client to https://llm.fixcloud.ai/v1 to migrate in seconds without code rewrites.
https://llm.fixcloud.ai/v1 endpoint.